
Discover segmentation by chunking source rows
Sometimes, a CSV file might be huge to absorb. In this case you can choose to segment on the number of rows to improve total load speed
Objective
Sometimes, a CSV file might be huge to absorb. In this case you can choose to segment on the number of rows to improve total load speed.
Requirements
Before using this segmentation type, some points must be checked:
1. Avoid generating too many tasks in the same stage.
To ensure the Data Processing Engine (DPE) performs well, we advise against having stages with more than 500 tasks.
This is not a hard limit but performance degradations can be observed with increasing number of tasks above 500. In order to reduce the number of tasks, you can set a higher bucket size, so that each task will manage more rows. (meaning less tasks at the end).
Keep in mind that for each task, the source CSV file will be uploaded again from a datastore temporary bucket into each worker. so if your csv file is huge, you might want to keep the number of tasks low. Ideally the number of tasks should be the number of workers the job possesses.
2. Is there enough CPU on the destination database?
- Keep in mind that
insertoperations are CPU intensive for your DBMS. - For example, if your database has only 1 CPU, it's probably a bad idea to set 6 workers to insert simultaneously against the DBMS instance...
General Rule: 1 CPU should be available for each worker running simultaneously.
Compatibility
How to use this type of segmentation?
Here is a quick view between the visible mode and the advanced JSON mode.
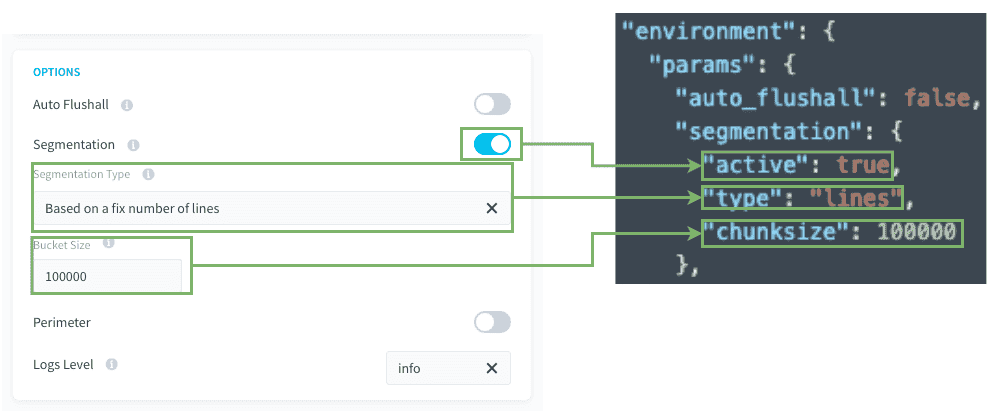
Bucket size / Chunksize: Set how many rows will be absorbed for each task.
Load actions
The Load action source will be the base of the segmentation.
Custom actions
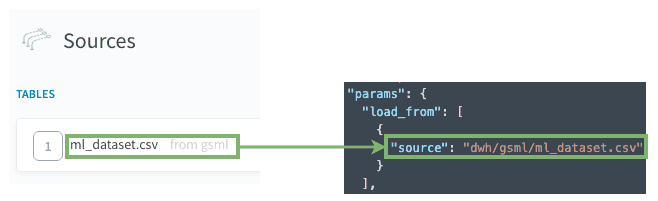
Make sure that the key params.load_from[0].source indicates the address of the source:
dwh/SOURCE_NAME/FILE_NAME or TABLE_NAME
Please check the previous screenshot for an example of the advanced JSON mode.
How does it work behind the scenes?
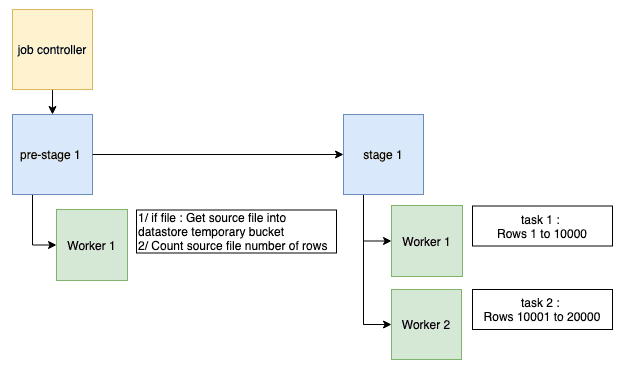
If your action has a segmentation Based on a fixed number of lines, when executing the action, or the action in a workflow, it will execute:
- A hidden pre-stage that gets the CSV source file, count its number of rows, then put it in an object-store temporary bucket.
- The Job Controller splits the action into multiple tasks, each with a different row chunk to ingest.
- Then each worker executes each task one by one.
Go further
If you need training or technical assistance to implement our solutions, contact your sales representative or click on this link to get a quote and ask our Professional Services experts for a custom analysis of your project.
Ask questions, give your feedback and interact directly with the team building the Data Platform on the dedicated Discord channel.
If you need support with your OVHcloud services, create a request in our Help Centre.
Join our community of users.